Encryption at rest converts stored data into ciphertext so it stays unreadable without the correct key, whether that data sits on a disk, in a database, or inside a backup archive. The best-practice verdict is simple to state and harder to execute: encrypt sensitive stored data using authenticated algorithms, and keep key custody separate from the data itself. That separation, not the encryption algorithm, is where most real-world security gains and most operational headaches originate.
TL;DR:
- Full-disk encryption is effective against physical device theft, but offers no protection once the system is unlocked and running.
- Application-level encryption offers the strongest confidentiality but requires complex key management, especially for compliance-sensitive data.
- Using envelope encryption with cloud KMS or HSMs enables scalable key rotation and separation of duties, reducing operational risks.
- Authentic modes like AES-GCM or AES-CCM are essential for encrypting stored data, with AES-256 recommended for regulated or highly sensitive information.
- Most effective security combines multiple layers, such as disk encryption for hardware theft and application-level encryption for insider threats, tailored to the attacker profile.
Data Encryption at Rest: Methods and Where Each One Runs
Encryption at rest is not a single technology. It is a set of layers, each protecting against a different failure mode, and choosing the wrong layer for your threat model leaves gaps that feel secure until an incident proves otherwise.
Full-disk and volume encryption (BitLocker on Windows, LUKS on Linux) encrypts an entire storage volume at the block level. It runs transparently once unlocked, which makes it invisible to applications and easy to deploy fleet-wide. Its primary job is defending against physical theft: a stolen laptop or a decommissioned drive that lands in the wrong hands. Security guidance from UCI’s information security office recommends full-disk encryption specifically for portable devices, because once the machine is powered off, the entire volume is opaque without the unlock credential. Its weakness is equally clear: once the system is running and unlocked, an attacker with application-level or OS-level access sees the same plaintext everyone else does.
File- and folder-level encryption narrows the scope. Instead of protecting a whole volume, it protects individual files, which matters when data needs to travel: a file copied to a USB drive, synced to cloud storage, or emailed as an attachment keeps its encryption regardless of where it lands. This granularity is useful for compliance scenarios where only specific documents (contracts, tax records, health files) need protection, not an entire filesystem.
Database-level encryption, most commonly Transparent Data Encryption (TDE), protects the actual database files, including backups and transaction logs, without requiring changes to queries or application code. Microsoft’s documentation on TDE describes it as encrypting the database at the file level while relying on certificates or an external key vault to protect the encryption key itself. TDE is a strong default for regulated data stored in SQL Server, Azure SQL, or similar platforms, but it does not protect data once a query has decrypted it into an application’s memory or logs. Column- and table-level encryption go further, encrypting specific sensitive fields (Social Security numbers, payment details) independently, which limits blast radius even if the broader database is compromised.
Application-level, or client-side, encryption happens before data ever reaches the storage layer. The application encrypts the payload, and the storage system, whether that’s a database, an object store, or a third-party SaaS platform, only ever sees ciphertext. This is the strongest model for confidentiality because it assumes the storage layer itself might be compromised or subpoenaed, and the keys never live anywhere near it. It’s also the most demanding to build correctly: key distribution, versioning, and search/indexing on encrypted fields all become the application’s problem.
Hardware-based encryption, delivered through self-encrypting drives (SEDs), performs encryption in dedicated silicon on the drive controller. It’s fast, since it adds essentially no CPU overhead, and it’s a solid baseline against physical media theft. Its limitation is scope: SEDs protect the drive when it’s out of the machine, not data in transit or an attacker who has already authenticated into the running system.
A short summary of what each method actually stops:
- Full-disk/volume encryption: stops physical device theft, not live-system access.
- File-level encryption: protects data as it travels or gets copied.
- Database TDE: protects database files and backups without app changes.
- Application-level encryption: protects against a compromised storage layer or provider.
- Hardware SEDs: fast, low-overhead protection against media theft specifically.
Which Encryption Layers Should You Actually Use?
Picking layers starts with naming the attacker you’re defending against, not with picking the encryption method that sounds most rigorous. A retail chain worried about stolen point-of-sale hardware has a different problem than a fintech startup worried about a compromised cloud storage bucket, and the right layer differs accordingly.
- Lost or stolen hardware (laptops, drives, mobile devices) is solved primarily by full-disk encryption or self-encrypting drives. Nothing else is usually necessary for this specific threat.
- A compromised cloud storage account or misconfigured bucket requires encryption that doesn’t depend on the storage provider holding the only key, which points toward customer-managed keys (CMKs) at minimum, and application-level encryption for the most sensitive fields.
- An insider or compromised application server with database access defeats most storage-level encryption outright, since the running application decrypts data to serve queries. Column-level or application-level encryption of the specific sensitive fields is the only layer that helps here.
- A subpoena or third-party legal request to a cloud provider is mitigated only by application-level encryption where the provider never possesses the decryption key at all.
Layering matters because no single method covers every attacker profile. A minimum viable posture for most business systems combines full-disk encryption on endpoints, TDE or equivalent at the database layer, and CMKs for anything cloud-hosted. Regulated data, healthcare records, payment card data, or anything under attorney-client privilege usually pushes teams toward application-level encryption regardless of what the platform offers by default, because compliance frameworks increasingly expect the platform vendor to be locked out of plaintext access entirely.
Cloud-provider default encryption, using platform-managed keys, is genuinely sufficient for a large share of workloads: internal tools, non-regulated analytics data, and systems where the provider’s own security posture is already trusted. Microsoft Learn’s guidance on encryption at rest notes that platform-managed keys require zero configuration and handle rotation automatically, which is exactly why they’re the right default until a specific compliance or threat-model reason says otherwise.
Pro Tip: Write down your attacker profile before you write a single line of encryption code. Teams that skip this step almost always over-invest in application-level encryption for data that only ever needed full-disk protection, and burn weeks of engineering time doing it.
Key Management, KMS Integration, and Envelope Encryption
Encryption is easy. Key management is where most real-world failures happen, and it’s usually not the algorithm that breaks, it’s the process around the key.
The first decision is service-managed keys versus customer-managed keys. Platform-managed keys, offered by every major cloud provider, encrypt data automatically with no setup and handle rotation behind the scenes. Customer-managed keys (CMKs) hand control back to the organization: you decide rotation schedules, access policies, and revocation procedures, but you also own the operational burden of getting all of that right. As Microsoft Learn frames it, CMKs trade zero-configuration convenience for granular control over the key lifecycle, and that trade only pays off when compliance or threat-model requirements demand it.
Almost every serious KMS integration, whether AWS KMS, Azure Key Vault, Google Cloud KMS, or HashiCorp Vault, relies on a pattern called envelope encryption. Instead of using one master key to encrypt every piece of data directly, the system generates a data encryption key (DEK) for the actual payload, then wraps that DEK with a key encryption key (KEK) held in the KMS or hardware security module (HSM). The Kubernetes documentation on KMS providers describes exactly this pattern for encrypting cluster secrets, and it’s the standard architecture for a reason: it lets you rotate or re-wrap the KEK without touching every encrypted record, and it limits how often the most sensitive key material is ever exposed.
Where should the KEK actually live? Three common options, each with a different trust and cost profile:
- A hardware security module (HSM) offers the strongest isolation, since keys generally never leave tamper-resistant hardware, but costs the most and adds latency.
- A managed cloud KMS (AWS KMS, Google Cloud KMS, Azure Key Vault) balances strong isolation with far lower operational overhead than running your own HSM.
- A self-hosted vault (HashiCorp Vault or similar) gives full control for organizations with strict data-residency requirements but shifts all the operational risk in-house.
Key lifecycle work doesn’t end at generation. Rotation needs a schedule, not just a reaction to suspected compromise, and OWASP’s Cryptographic Storage Cheat Sheet is direct on one point: never store keys in the same system or filesystem as the data they protect. That single misconfiguration, co-locating keys and data, shows up repeatedly in post-incident reviews. Research from the RSA Conference on encryption practices makes a related point worth sitting with: operational key management is often harder than the cryptography itself, and mistakes in provisioning, rotation, and access policy cause more real breaches than weak algorithms do.
If you’re running Kubernetes, this is not optional guidance to defer. Kubernetes explicitly recommends KMS v2 for encrypting cluster secrets at rest, because it generates derived, single-use DEKs and outperforms the deprecated v1 provider on both security and speed. Clusters still running v1 should plan a migration, which requires careful re-encryption and testing rather than a simple config flip.
Which Encryption Algorithm Should You Actually Use?
For symmetric encryption of stored data, AES remains the standard, and the mode matters as much as the key length. Use an authenticated mode, specifically AES-GCM or AES-CCM, rather than older unauthenticated modes like CBC without a separate MAC. Authenticated modes detect tampering as part of decryption itself, which closes off a class of attacks where ciphertext is modified and the corruption goes unnoticed until it’s too late.
Key length depends on the risk tier: AES-128 is adequate for most commercial data, while AES-256 is the common choice for regulated or highly sensitive data where compliance frameworks specify it explicitly. The performance gap between the two is small enough on modern hardware that defaulting to AES-256 for anything sensitive is rarely a costly decision.
For asymmetric operations, elliptic-curve cryptography (ECC) using curves like P-256 or Curve25519 gives equivalent security to RSA at far smaller key sizes, which matters for performance-sensitive key-wrapping operations. Where RSA is still used, proper padding (OAEP, not raw or legacy PKCS#1 v1.5) and a minimum key size of 2048 bits, moving to 3072 for longer-lived data, are standard requirements.
A short checklist for algorithm and mode decisions:
- Use AES-GCM or AES-CCM for symmetric encryption of stored data, as these authenticated modes provide integrity.
- Use AES-256 for highly sensitive or regulated data; AES-128 is commonly used otherwise.
- Use ECC (P-256, Curve25519) for asymmetric key-wrapping where performance matters.
- Always use a cryptographically secure random number generator for key and IV generation.
For the authoritative version of all of this, NIST SP 800-131A Rev. 2 sets out approved algorithms, key sizes, and the transition timelines for deprecating weaker options, and it’s the document compliance auditors will actually check against. OWASP’s Cryptographic Storage Cheat Sheet reinforces the same guidance in more implementer-friendly language, with concrete advice on where in an architecture encryption should actually happen.
How Much Does Encryption Slow Down Your System?
Performance impact varies enormously by layer, and guessing instead of measuring is how teams end up either over-provisioning hardware for a phantom problem or shipping a slow feature nobody diagnosed correctly.
Full-disk encryption on modern hardware with AES-NI instruction support adds overhead low enough that it’s rarely noticeable in practice. Database-level TDE adds a small, consistent CPU cost on read and write operations, generally acceptable for transactional workloads but worth benchmarking on write-heavy systems. Application-level encryption carries the highest variable cost, since it touches every field individually and often breaks native indexing and search unless deterministic encryption or specialized searchable-encryption schemes are used deliberately.
An operational test checklist before any encryption rollout goes to production:
- Benchmark read/write throughput before and after enabling encryption at each layer, under realistic load, not synthetic single-thread tests.
- Run full restore tests from encrypted backups, not just backup completion checks. A backup that completes but can’t be restored is not a backup.
- Load-test key rotation specifically, since rotating a KEK while the system is under production traffic can reveal latency spikes that idle testing misses.
- Verify access logging captures every decryption event with enough context to reconstruct who accessed what and when.
The most common pitfalls aren’t algorithmic. They’re operational: keys stored alongside the data they protect, backup encryption that nobody has tested a restore against, IAM permissions broad enough that half the engineering team can call the KMS decrypt API, and logging gaps that make a breach investigation impossible after the fact. Monitoring should track KMS access patterns specifically, alerting on unusual volumes of decryption calls, access from unexpected regions or service accounts, and any spike outside normal application behavior.
Pro Tip: Set a decryption-rate baseline in your monitoring within the first week of production. Most teams only discover what “normal” looks like after an incident already forced them to ask the question retroactively.
Backup Encryption and Ransomware Resilience
Encrypted backups solve one problem and create another: they protect stored data from theft, but if the backup and its key sit in the same blast radius as a ransomware attack, you’ve built an elaborate lock with the key taped to the door.
CISA’s guidance on encrypting business data is explicit that offline or air-gapped backup copies, kept separate from production networks, are a critical defense against ransomware specifically, alongside encrypting the backups themselves and regularly testing that restores actually work. A backup strategy without a tested restore process is a false sense of security wearing a compliance checkbox.
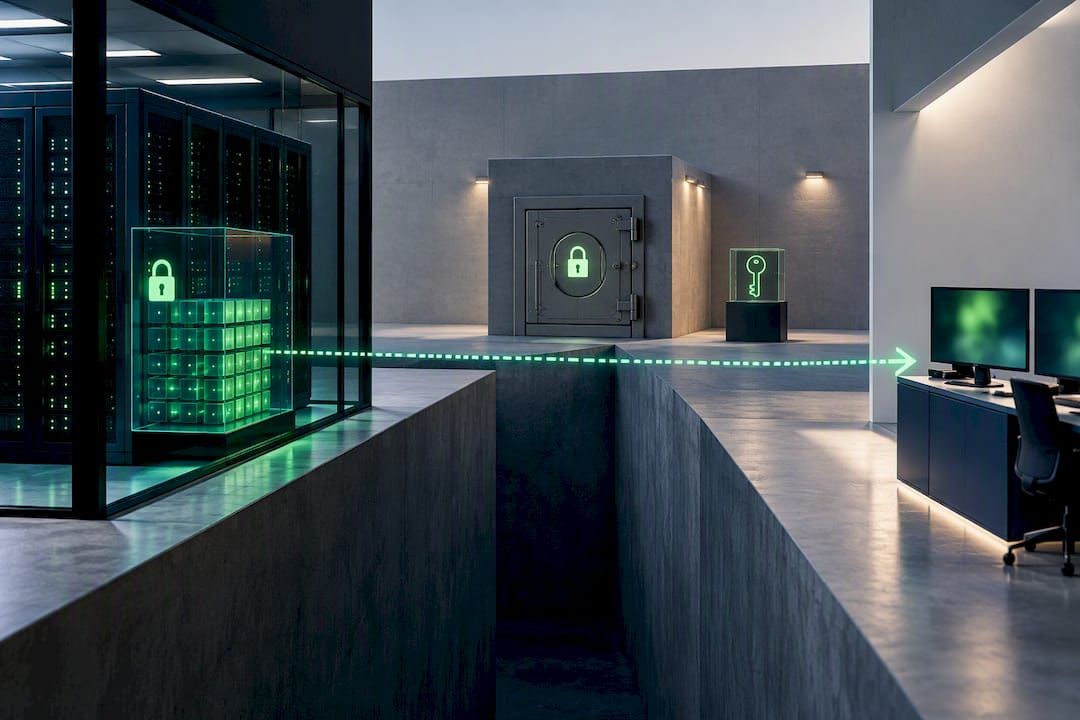
Key rotation for existing backups raises a real trade-off. Re-wrapping (rotating only the KEK while leaving the underlying DEK-encrypted data untouched) is fast and low-risk, since it never touches the bulk data. Re-encrypting everything with a fresh DEK is more thorough, closing off any residual exposure from a suspected key compromise, but it’s slow and resource-intensive at scale. Most organizations default to re-wrapping on a schedule and reserve full re-encryption for confirmed compromise events.
A practical backup and recovery checklist:
- Keep at least one offline or immutable backup copy, isolated from the production network entirely.
- Store backup encryption keys separately from both the backup media and the production KMS.
- Test full restores on a recurring schedule, not only after a suspected incident.
- On key compromise: revoke the affected key, restore from a verified clean offline backup, then rotate both KEKs and DEKs before resuming normal operations.
Partner platforms focused on backup tooling, such as backup plugin options for platforms like Shopware, illustrate how automated, scheduled backup strategies get built for specific stacks, a useful reference point when designing your own restore cadence.
How Bitecode Approaches Encryption at Rest in Practice
Modular software components can implement envelope encryption as a default pattern, such as a per-record DEK wrapped by a KEK held outside the application, with KMS integration handled through a common module framework. Key custody should never sit alongside the data it protects, matching the separation principle that governs every recommendation in this guide.
For teams building out compliance-sensitive systems, Bitecode’s own writing on financial data security and fintech-specific security practices covers the compliance angle in more depth, while the PII data masking guide addresses the complementary strategy of reducing what sensitive data you store in the first place, before you even reach the question of how to encrypt it.
A short deploy-time verification checklist worth running before any encrypted system ships:
- Confirm keys and encrypted data live in physically and logically separate systems.
- Run at least one full backup restore test against the production key hierarchy.
- Establish a performance baseline for read/write operations at each encryption layer.
- Document the key rotation schedule and who holds emergency revocation authority.
Encryption Is a Layer, Not a Strategy
Encryption at rest gets treated too often as a finish line, something you check off once TDE is enabled or a KMS integration ships. It isn’t. It’s one control in a program that needs least-privilege access, active monitoring, and a secure development lifecycle sitting alongside it, or the encrypted data is protected against exactly one threat while remaining wide open to a dozen others.
The most overlooked recommendation in this entire space, and the one OWASP states plainly, is that the strongest control is not storing sensitive data you don’t need. Encryption is what you do when storage is unavoidable, not a substitute for minimizing what gets stored. Treat it as a repeatable item on every deployment checklist, not a one-time architectural decision made during a project kickoff and forgotten afterward.
— Bitecode
Build Encrypted Systems Without Starting From Zero
Designing envelope encryption, wiring up KMS integration, and building tested backup and restore procedures from scratch typically means months of specialized engineering work before a system is even feature-complete. Bitecode starts differently: its modular components arrive with encryption and key-separation patterns already built in, so custom business software projects begin with the security architecture in place rather than as a bolt-on afterthought.
That matters most for teams handling financial data, where the Financial Module applies the same key-custody separation discussed throughout this guide to transactions, ledgers, and audit trails. Organizations deploying on their own infrastructure can also route sensitive workloads through advanced cloud applications built with CMK-based key management from the start, rather than retrofitting it after a compliance review flags the gap.
If your team is scoping a system that needs encrypted storage, tested backups, and KMS integration handled correctly the first time, start a conversation through Bitecode’s services page to discuss what a modular build looks like for your specific compliance and threat-model requirements.
Sources
- Encryption at rest - Microsoft Learn
- Cryptographic Storage Cheat Sheet - OWASP
- Encrypt business data - CISA
- NIST SP 800-131A Rev. 2
FAQ
How Is Data Encrypted at Rest?
Data is converted to ciphertext using an algorithm like AES paired with a secret key, and it happens at a specific layer, disk, file, database, or application, chosen based on the threat being defended against. The key itself is typically managed through envelope encryption, where a KEK held in a KMS or HSM wraps the DEK that actually encrypts the data, as described in Kubernetes’s own KMS provider documentation.
What Is the Best Encryption for Data at Rest?
AES using an authenticated mode, specifically AES-GCM, is the standard recommendation for encrypting stored data, per OWASP’s Cryptographic Storage Cheat Sheet. AES-256 is the common choice for regulated or high-sensitivity data, while AES-128 remains acceptable for most other commercial use cases.
What Type of Encryption Is Usually Used With Data at Rest?
Symmetric encryption, almost always AES, is the standard for encrypting the bulk data itself at rest because it’s fast enough for large volumes and files. Asymmetric algorithms like RSA or ECC are typically used only for wrapping the symmetric key, not for encrypting the data directly.
What Are the Levels of Encryption for Data at Rest?
Storage security generally layers across three levels: full-disk or hardware encryption protecting physical media, database or file-level encryption (including Transparent Data Encryption) protecting stored records and backups, and application-level encryption protecting specific sensitive fields before they ever reach storage. Most systems combine at least two of these levels depending on the sensitivity of the data involved.
Should Small Teams Use Customer-Managed Keys or Platform-Managed Keys?
Platform-managed keys are the right default for most teams, since they require zero configuration and handle rotation automatically, according to Microsoft Learn. Customer-managed keys make sense once compliance requirements or a specific threat model call for direct control over rotation, access policy, and revocation.