A circuit breaker stops repeated calls to a failing dependency so the system fails fast and avoids cascading outages. It belongs in any architecture where a service makes synchronous remote calls to something that can slow down, time out, or fall over: third-party APIs, databases under load, or downstream microservices. The trade-off is real: better failure isolation in exchange for added configuration complexity and the risk of tripping on noise instead of genuine outages.
TL;DR:
- Circuit breakers are essential when dependencies can slow down or fail, preventing resource exhaustion and cascading outages in microservice architectures.
- Proper configuration involves setting failure thresholds, windows, reset timeouts, and test request limits, with iterative tuning based on observed system behavior.
- Failures like 500 errors or connection timeouts should trip the breaker, while normal errors such as 404s typically should not count against it.
- Implementing the breaker at the application or platform level depends on organizational structure, with careful observability of states, failures, and latencies crucial for effective operation.
- Using a breaker without complementary patterns like retries, fallbacks, or bulkheads can lead to silent failures and misdiagnosed issues; operational discipline is key.
What Problem Does the Circuit Breaker Pattern Actually Solve?
A local function call fails in microseconds and fails cleanly. A remote call over a network can fail in a dozen different ways, and half of them look identical to success until the timeout clock runs out. That distinction is the entire reason the circuit breaker pattern exists.
When a downstream dependency slows down instead of cleanly erroring out, every caller waiting on it holds a thread, a connection, or a memory buffer open. Multiply that across hundreds of concurrent requests and a single sluggish payment service can exhaust the thread pool of every service that calls it. This is how one slow dependency becomes a full outage. Microsoft’s Azure Architecture Center frames circuit breaker pattern design around exactly this scenario: an application repeatedly attempting an operation likely to fail, tying up resources it needs elsewhere.
Retry logic, without a breaker attached, makes this worse, not better. A naive retry loop on a struggling service adds load precisely when that service can least handle it. This is the mechanism behind most retry storms.
Three failure patterns matter most for microservices teams:
- Cascading failures, where one dependency’s slowdown ties up resources across every upstream caller.
- Resource exhaustion, where thread pools, connection pools, or memory buffers fill up waiting on responses that never arrive in time.
- Retry amplification, where well-intentioned retry logic multiplies request volume against an already-struggling service.
Timeouts alone catch the “how long do I wait” problem but not the “should I even bother trying” problem. That second question is what a circuit breaker answers.
How the Circuit Breaker Pattern Works
At its core, a circuit breaker is a stateful object that wraps a protected call and decides, before that call ever executes, whether to let it through. Martin Fowler’s original description frames it as an object that monitors for failures, and once failures reach a threshold, trips to stop further attempts entirely, resetting itself later through a trial period rather than staying broken indefinitely, per Martin Fowler’s Circuit Breaker essay.
That monitoring behavior depends on a handful of configuration knobs, and getting these right is most of the tuning work:
- Failure threshold: the number or percentage of failed calls that trips the breaker.
- Sliding or rolling window: the time span or call count over which failures are measured, so a burst two hours ago doesn’t count against current health.
- Reset timeout: how long the breaker stays open before allowing a trial call.
- Permitted test requests: how many calls get through during the half-open probing phase, and what result moves the breaker back to closed or open.
None of this replaces the other resilience patterns; it coordinates them. A timeout defines how long a single call is allowed to hang. A retry decides whether to try again. A fallback defines what happens when the answer is no. A bulkhead pattern isolates the thread pools and connections for one dependency so its failure can’t starve every other call in the system. The circuit breaker sits above all of them, deciding when it’s even worth attempting the call in the first place.
Pro Tip: Build the breaker around the call, not around the retry loop. If retry logic sits inside the breaker’s scope, a single “attempt” can quietly consist of five retries, and your failure counter will undercount how often the dependency is actually struggling.
Skipping the breaker and relying on retry and timeout alone is a common circuit breaker vs retry mistake. Retry answers “should I try this specific call again,” while the breaker answers “is this dependency healthy enough to bother trying at all.” Teams that treat these as interchangeable end up with systems that retry their way into an outage instead of avoiding one.
Closed, Open, and Half-Open: The State Machine Explained
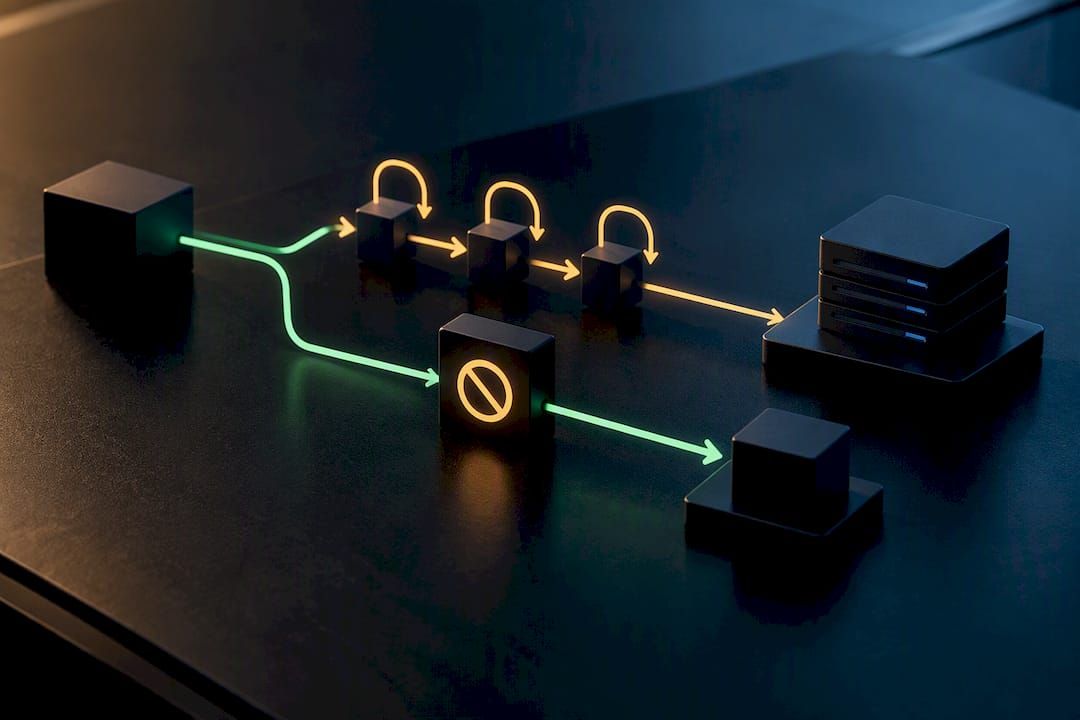
Every circuit breaker implementation, regardless of library, runs through the same three states.
- Closed. This is normal operation. Calls pass through to the dependency, and the breaker tracks failures inside its configured window, either as a raw count or as an error rate. Once the failure threshold is crossed inside that window, the breaker trips to open.
- Open. Calls fail immediately without touching the dependency, typically returning a fallback response or a specific exception the caller can handle. This is the fail-fast behavior that makes the pattern valuable: no wasted timeouts, no held threads. The breaker stays open for a configured reset timeout, after which it moves to half-open.
- Half-open. The breaker allows a limited number of trial requests through to test whether the dependency has recovered. If those calls succeed, the breaker closes and normal traffic resumes. If they fail, it reopens and the reset timer starts over.
Two common variants shape how the closed state actually measures trouble. Count-based thresholds trip after a fixed number of failures, say 10 failed calls in a row, which is simple to reason about but can misfire under low traffic. Percentage-failure thresholds trip when the error rate crosses a set percentage within the window, which behaves better at scale because it accounts for volume rather than raw counts. Adaptive thresholds, less common but increasingly available in newer libraries, adjust sensitivity based on recent traffic patterns rather than a fixed configuration.
The AWS Prescriptive Guidance implementation of this pattern uses a central status store with a time-to-live field to manage exactly this open-to-half-open transition across stateless functions, which matters once you move past a single monolithic breaker instance, per AWS’s serverless circuit breaker guidance.
Configuring and Implementing a Circuit Breaker in Production
Not every failure should count against the breaker. A 404 from a well-formed request that legitimately doesn’t exist is not a sign the dependency is unhealthy. A 500, a connection timeout, or a refused connection is. Error classification is the first configuration decision, and it’s the one teams skip most often, then wonder why their breaker trips on traffic that was never actually a problem.
Once classification is settled, the actual library choice for JVM-based microservices comes down to a short list:
- Resilience4j is the current standard for Java and Kotlin services, built as a lightweight, functional alternative with modules for circuit breaking, rate limiting, retry, and bulkheading that compose cleanly together.
- Spring Cloud Circuit Breaker provides an abstraction layer over implementations like Resilience4j, useful for teams already standardized on the Spring ecosystem who want a consistent API regardless of the underlying engine.
- Hystrix, Netflix’s original circuit breaker library, is worth knowing as historical reference. It popularized the pattern in the microservices world but has been in maintenance mode for years, and Baeldung’s overview of the pattern confirms it’s no longer the recommended starting point for new systems.
The tuning process itself works best as a small experiment rather than a guess. Start conservative: a higher failure threshold and a longer window than you think you need. Deploy, watch rejection rates, latency percentiles, and downstream error rates, then tighten gradually. Microsoft’s cloud-native architecture guidance recommends exactly this iterative approach, measuring toward the smallest acceptable failure rate while minimizing false trips, per its application resiliency patterns documentation.
Pro Tip: Make your retry logic circuit-aware. Check breaker state before entering a retry loop; if the breaker is open, skip straight to fallback. Retrying against an open breaker wastes cycles on a call you already know will fail, and it defeats the entire point of fast failure.
Monitoring and Observability for Circuit Breakers
A breaker that fails silently is worse than no breaker at all, because it hides the exact failure it was built to surface. Azure’s architecture guidance is explicit that breaker state needs to be exposed for monitoring, not buried inside application logic, per its circuit breaker documentation.
The signals worth tracking on every breaker instance:
- Current state (closed, open, half-open) as a time series, not just a snapshot.
- Failure count and success rate inside the active window.
- Request rejection count while the breaker is open.
- Latency percentiles for calls that do get through.
Alert on sustained open state lasting longer than expected, on rejection rates that spike without a corresponding downstream incident, and on frequent half-open flapping. That last signal in particular tends to mean the thresholds are mistuned rather than the dependency genuinely recovering and failing in a loop, an insight worth building into your alert runbooks directly from the Azure guidance on breaker telemetry. Correlating breaker state changes against downstream service health endpoints and logs is usually the fastest way to tell a real outage from a false trip.
Common Circuit Breaker Pitfalls and How to Avoid Them
Most circuit breaker failures in production trace back to a handful of repeat offenders, and nearly all of them are tuning problems rather than design flaws.
- False positives from traffic spikes hit count-based thresholds hardest; percentage-failure or rate-based thresholds smooth this out considerably.
- A single global breaker per dependency can turn one bad shard or partition into a total outage; shard-scoped or cell-scoped breakers reduce blast radius at the cost of more instances to manage, a trade-off worth making according to research on circuit breaker design pattern variations.
- Synchronous calls under load can exhaust a thread pool before the breaker even gets a chance to trip; pairing the breaker with asynchronous calls or a dedicated thread pool per dependency (the bulkhead pattern again) limits the damage window.
- Operators need a manual override. A force-open switch during a known incident, and a force-close for safe rollback testing, should exist outside the automatic state machine entirely.
None of these pitfalls are arguments against using the pattern. They’re arguments for treating breaker configuration as an operational responsibility, not a one-time setup task.
Circuit Breaker Code Examples and Architecture
A Resilience4j breaker in a Spring Boot service is typically a handful of configuration lines plus an annotation:
@CircuitBreaker(name = "paymentService", fallbackMethod = "fallback")
public PaymentResponse callPaymentService(PaymentRequest request) {
    return paymentClient.process(request);
}
The matching configuration sets the knobs discussed earlier: failure rate threshold, sliding window size, and wait duration in the open state.
Spring Cloud Circuit Breaker wraps this same logic behind a CircuitBreakerFactory abstraction, so the calling code doesn’t change even if the underlying engine does, and metrics export to Micrometer for dashboards without extra wiring.
The state machine itself, in pseudocode:
| Current state | Trigger | Next state |
|---|---|---|
| Closed | Failure rate crosses threshold in window | Open |
| Open | Reset timeout expires | Half-open |
| Half-open | Permitted test requests succeed | Closed |
| Half-open | Any permitted test request fails | Open |
A typical architecture sketch: an API gateway routes to a service, which calls a downstream dependency through a breaker-wrapped client. The breaker sits at the boundary, the gateway never sees the downstream failure directly, and the calling service returns a fallback response instead of hanging.
App-Level or Platform-Level: Where Should the Breaker Live?
Placing the breaker in application code gives fine-grained control over fallback logic and error classification, tuned per call site. Placing it at the platform level, inside a service mesh sidecar or API gateway, gives consistency across every service without each team reimplementing the same logic.
The right choice depends on team structure more than technology. Organizations with strong platform teams and many services benefit from mesh-level breakers; smaller teams with tighter service ownership often do better with app-level control, as detailed in this rubric for microservices communication decisions. Avoid breakers entirely for dependencies that never recover on their own or where synchronous correctness can’t tolerate a fallback response.
Need Help Implementing Resilient Architecture?
Configuring a breaker correctly across a dozen services, tuning thresholds without breaking things further, and wiring up the observability to trust the result takes real engineering time most internal teams don’t have to spare. Bitecode builds custom enterprise systems from modular, pre-built components, which means resilience patterns like circuit breakers get implemented and integrated with existing observability tooling without starting from a blank codebase.
This work fits teams facing a specific pressure: reliability issues that need fixing now, limited in-house SRE bandwidth, or a complex cross-system integration where fault tolerance can’t be an afterthought. Bitecode’s approach to advanced cloud applications covers exactly this kind of resilience-focused build, from breaker placement through the monitoring layer that tells you whether it’s working. If a reliability gap in your service-to-service calls is already costing you incidents, reach out to Bitecode to scope the work.
A Straight Answer on When Breakers Earn Their Complexity
The conventional advice treats circuit breakers as a default addition to any microservices system, and that’s where a lot of teams go wrong. A breaker adds real operational surface area: more state to monitor, more thresholds to tune, more ways for a misconfiguration to hide a genuine outage behind a false “fixed” signal.
The pattern earns its place specifically where synchronous calls to unreliable dependencies can exhaust shared resources. It’s less valuable, and sometimes actively counterproductive, wrapped around a dependency that’s rock solid or one where a fallback response makes no business sense. Teams that install breakers everywhere by default end up debugging their resilience layer instead of their actual system.
The teams that get the most out of this pattern are the ones who treat threshold tuning as an ongoing operational task, not a one-time setup, and who watch half-open flapping as closely as they watch outright failures. That discipline, more than the library choice, determines whether a circuit breaker actually reduces incidents or just adds a new category of them.
— Bitecode
Sources
Start with the Azure Architecture Center’s circuit breaker pattern for the canonical definition and monitoring guidance. Martin Fowler’s original essay explains the state machine’s conceptual roots. AWS’s prescriptive guidance shows a serverless implementation, and the ORNL resilience design patterns paper frames the broader trade-offs between resilience and performance.
- Circuit Breaker pattern - Azure Architecture Center
- Circuit Breaker — Martin Fowler
- Circuit breaker pattern - AWS Prescriptive Guidance
FAQ
How Does a Circuit Breaker Pattern Work?
A circuit breaker wraps a protected call and tracks failures against a configured threshold inside a time or count window. Once that threshold is crossed, it moves to an open state and fails calls immediately, then periodically allows trial requests through a half-open state to check whether the dependency has recovered, per Martin Fowler’s description of the pattern.
What Is the Circuit Breaker Design Pattern?
It’s a resilience design pattern that stops an application from repeatedly calling an operation that’s likely to fail, protecting shared resources like threads and connections from being exhausted by a struggling dependency. The Azure Architecture Center frames it as working alongside retry, timeout, and fallback patterns rather than replacing them.
What Is the Circuit Breaker Pattern in C#?
The pattern works identically in C# to any other language: it’s a stateful wrapper around a remote call that tracks failures and transitions between closed, open, and half-open states. .NET teams typically implement it through Polly, a resilience library that provides the same closed/open/half-open behavior described in Microsoft’s application resiliency guidance.
What Is the Purpose of the Circuit Breaker Pattern in Microservices?
Its purpose is preventing cascading failures when one service’s slowdown would otherwise tie up threads and connections across every service that calls it. In a microservices architecture with many synchronous service-to-service calls, this containment is what keeps one bad dependency from taking down the whole system.
When Should I Use a Circuit Breaker Instead of Just a Retry?
Use retry for transient, short-lived failures where trying again is likely to succeed; use a circuit breaker when a dependency is failing consistently enough that retrying wastes resources without improving outcomes. The two work best combined, with retry logic checking breaker state first so it never fires against an already-open circuit.